Proxy Server API: What It Is and How to Choose One

Victor
Posted on 26 October 2026


Your remote scheduler can sign in to the scheduling platform, but the appointment-sync tool keeps failing. The vendor says its API is available. Your IT contractor suspects the proxy. Meanwhile, staff are checking calendars manually, and nobody can explain whether the problem is a credential, a blocked destination, or a slow connection.
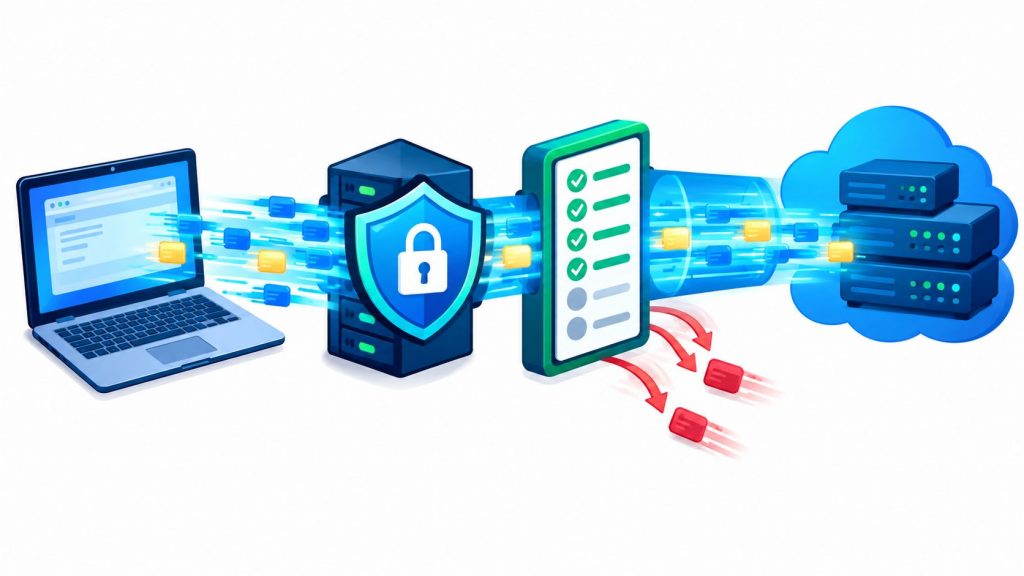
A proxy server API is an interface that routes an application's outbound traffic through an intermediary server. It can authenticate the caller, restrict destinations, and record connection activity. For a medical practice, that's useful when you need controlled access to approved systems. It isn't a replacement for individual staff accounts, secure devices, vendor permissions, or application-level audit trails.
The right choice starts with the job you're trying to accomplish. Controlling a scheduling integration's outbound connections usually calls for a conventional forward proxy. Collecting usable records from difficult third-party websites may justify a managed data API instead. Custom networking and policy requirements may require an engineer to build and maintain the integration.
Buying rule: Evaluate the cost of a completed, usable workflow, not just the advertised price of traffic.
For practice managers evaluating remote healthcare staff, the practical questions are straightforward: which systems must staff and software reach, what happens when access fails, who owns recovery, and how much staff time does the arrangement consume?
Table of Contents
A proxy server API sends an application's outbound requests through an intermediary that applies authentication, destination policy, and logging before forwarding permitted traffic. Think of a hotel concierge: you make a request, the concierge checks the house rules, places the call using the hotel's line, and connects you if it's allowed.
The analogy has a limit. For encrypted traffic, the concierge generally connects the call rather than listening to the conversation. A proxy can control the connection without understanding the information passing through it.

As the MDN documentation for CONNECT explains, the client names a destination using a host-and-port target, such as CONNECT api.example.com:443 HTTP/1.1, and the proxy opens a TCP connection before relaying bytes in both directions. TLS, the encryption protecting HTTPS, runs through that tunnel between the client and destination.
Say your remote scheduling tool calls an approved vendor's API. The proxy can identify the calling application, check the vendor hostname and port, and record whether the tunnel opened. Without TLS termination, it can't read the appointment details or verify that the application requested the correct patient's record.
TLS termination means deliberately ending the encrypted connection at an intermediary so it can inspect traffic. That changes the trust model and creates additional certificate, privacy, and operational responsibilities. Don't enable it merely because a vendor offers an inspection checkbox.
A medical virtual assistant using a browser isn't necessarily using your application's proxy. Browser settings, background integrations, and office network routing can follow different paths, so ask IT to document which traffic passes through the control.
Every deployment needs clear answers to these questions:
Proxy API types compared by control, use and tradeoff
| Type | Who Chooses the Destination | Typical Use | Main Tradeoff |
|---|---|---|---|
| Forward proxy API | Your application | Controlled outbound access, egress filtering and logging | Adds a network hop and needs allowlist upkeep |
| Reverse proxy | Your own server configuration | Routing inbound requests to internal services | Solves inbound routing, not outbound access control |
| Datacenter rotating proxy API | Your application chooses the target; the provider chooses the exit address | High-volume collection from public pages at lower cost | Addresses are easier for target sites to block |
| Residential rotating proxy API | Your application chooses the target; the provider chooses the exit address | Geographic or reputation-sensitive access | Higher cost per gigabyte and sourcing needs legal review |
| Managed web-data API | Your application specifies the target; the provider handles routing, rendering and retries | Teams that need parsed records rather than raw pages | Less control and dependence on vendor pricing and coverage |
These categories describe different responsibilities. A forward proxy governs outbound connections from your software; a reverse proxy receives inbound connections to your own services. Buying one doesn't solve the other's problem, even when a vendor calls both products gateways.
Rotating proxies change the public-facing address used for requests. Datacenter addresses generally favor price and volume, while residential services may help when geographic or address-reputation checks affect access. Neither category guarantees that a target website will accept your requests.
A managed web-data API takes responsibility for more of the collection process. Depending on its documented capabilities, that may include browser rendering, retry handling, and extracting structured fields. You're buying an output-oriented service rather than just a route to the internet.
For an appointment scheduler, insurance verification specialist, or billing support worker, predictable access to approved vendor systems usually matters more than changing addresses. Rotation can trigger vendor security checks, interrupt persistent sessions, or complicate investigations into unfamiliar sign-ins.
A practice collecting public directory information has a different problem from a practice connecting to an EHR API. Even then, check whether the information is available through an authorized export or supported integration before building a collection pipeline.
Changing an address doesn't create permission to access a system or collect its contents.
Confirm website terms, applicable law, and residential address sourcing with qualified counsel where relevant. For patient-facing operations, prefer a supported integration over a workaround that staff must repeatedly repair.
A production proxy needs more than a forwarding function. Its supporting components determine whether a bad credential produces a useful error or an unexplained outage.
Proxy-Authorization and issues the appropriate challenge. RFC 9110 specifies CONNECT's explicit destination port and proxy-authentication semantics, including HTTP 407 for missing or invalid proxy credentials.
The request path should be easy to trace:
The following is a reference design, not a required HTTP proxy interface. A raw CONNECT proxy doesn't need a JSON request endpoint; a vendor may provide a separate API for session management and forwarding.
Reference endpoints for a proxy API
| Endpoint | Method | Purpose | Typical Response |
|---|---|---|---|
/v1/sessions |
POST | Create a session with destination policy and lifetime | Created session identifier and expiry |
/v1/sessions/{id} |
GET | Check session state, expiry and usage | Success response with state fields |
/v1/sessions/{id} |
DELETE | Close the session and release connections | Confirmation that the session closed |
/v1/requests |
POST | Send one request through an active session | Upstream status with proxy metadata headers |
/v1/usage |
GET | Report request, byte and error counts for a billing period | Success response with usage totals |
/v1/health |
GET | Confirm the proxy and egress pool are reachable | Success response with component status |
Session creation fixes policy and lifetime; the request endpoint carries application work. Treat session identifiers as expiring credentials, and avoid adding management endpoints that nobody needs.
For custom development, use API design best practices to define stable error responses and ownership boundaries. A small internal deployment may need only forwarding and health checks.
Start with a read-only request to an approved test endpoint. Don't make an appointment creation or claim submission your first connectivity test.
For Python Requests, provide a proxy mapping and explicit connection and read timeouts. This example reads both the target and proxy configuration from the environment; the timeout values are illustrative settings, not production recommendations.
import os
import requests

response = requests.get(
    os.environ["TARGET_API_URL"],
    proxies={"https": os.environ["PROXY_URL"]},
    timeout=(5, 30),
)
print(response.status_code)
For curl, pass the proxy separately from the target. Load these environment variables through your approved secrets mechanism, and run the command where shell tracing and process inspection won't expose credentials.
curl --proxy "$PROXY_ADDRESS"
  --proxy-user "$PROXY_CREDENTIALS"
  --connect-timeout 5
  --max-time 30
  "$TARGET_API_URL"
In Node.js, an HTTPS client can use the https-proxy-agent package:
import https from "node:https";
import { HttpsProxyAgent } from "https-proxy-agent";

const agent = new HttpsProxyAgent(process.env.PROXY_URL);

const request = https.get(
  process.env.TARGET_API_URL,
  { agent },
  response => {
    console.log(response.statusCode);
    response.resume();
  }
);

request.setTimeout(30000, () => request.destroy(
  new Error("Request inactivity timeout")
));
request.on("error", error => console.error(error.message));
That Node.js timeout is an inactivity safeguard, not a complete connection and wall-clock deadline policy. Production code should separately bound connection setup and total execution.
Load credentials from a secrets store or protected environment configuration. A proxy URL may contain a username and password, so never print the complete URL in application logs or support tickets.
Use exponential backoff with jitter for eligible transient network errors and server failures, but don't blindly replay writes. A timeout after an appointment submission doesn't prove the appointment wasn't created; check the destination's supported idempotency or reconciliation mechanism.
Incident rule: Identify which system produced the error before changing credentials, increasing capacity, or restarting services.
Failure symptoms, likely layer and first check
| Symptom | Likely Layer | First Check |
|---|---|---|
407 Proxy Authentication Required |
Proxy credentials | Confirm Proxy-Authorization is sent and the key hasn't been rotated; don't retry automatically |
| TLS handshake error after tunnel opens | Client trust store or target certificate | Verify the certificate chain the target presents, since the proxy doesn't terminate TLS |
| Requests rejected at a local concurrency limit | Connection manager cap | Review concurrent tunnel count and raise the cap only after checking upstream capacity |
Provider error mappings differ. A policy refusal might appear as 403 or be wrapped as 502; record the actual behavior in your runbook rather than assuming either means an EHR outage.
For billing integrations, distinguish transport delivery from clearinghouse acceptance. Happy Billing's overview of the key features of billing clearinghouses provides useful workflow context for that discussion. Include these distinctions in your RESTful API testing scenarios, using synthetic records rather than live patient data.
Aggregate throughput hides the delays staff really experience. A scheduling integration can look healthy on average while a subset of requests waits long enough to interrupt patient calls.
The Wisconsin Proxy Benchmark identifies latency, proxy-hit ratio, byte-hit ratio, and client-error count as separate performance dimensions. For healthcare API traffic, measure connection behavior and reliability before treating caching as a benefit.
Proxy API metrics, what each reveals and how to measure it
| Metric | What It Reveals | How to Measure |
|---|---|---|
| Connection-establishment latency | Delay before the tunnel opens | Time from CONNECT to success, including upper-tail latency |
| Time to first byte | Proxy and upstream response delay | Time from request to first byte, separate from connection time |
| Total transfer time | Bandwidth and egress route limits | Compare identical payloads on direct and proxied paths |
| Proxy-hit ratio | Cache effectiveness on cacheable responses | Cache hits divided by cacheable requests only |
| Byte-hit ratio | Bandwidth reduction from caching | Cached bytes divided by total bytes for cacheable responses |
| Client-error count | Misconfiguration and authentication failures | Separate client errors from server failures |
| Tunnel establishment success rate | Health of the CONNECT path | Successful tunnel responses divided by attempts, per destination |
| Tail latency | Delays hidden by averages | Record upper percentiles by route and time window |
Track p95 and p99 latency alongside tunnel success, connection reuse, and timeout rates. Those percentiles reveal slow requests that an average can conceal.
Say a clinic's scheduling integration slows during morning sign-in because requests queue at the egress gateway. Confirm queue time before buying bandwidth: you may need additional connection capacity, shorter queue deadlines, or less simultaneous background work.
Increase concurrent tunnels gradually until errors or tail latency breach your service objective. A low-volume practice may learn more from routine timing logs than a large synthetic load test, but it still needs visibility during the hours staff depend on the integration.
Start with a positive destination allowlist. Permit approved hosts using their required schemes and ports, and deny everything else.
The OWASP SSRF Prevention Cheat Sheet recommends allowlisting trusted applications and enforcing destination restrictions when software only needs known services. For a practice, that might mean approved EHR, laboratory, payment, and identity endpoints, with internal administrative services and cloud metadata destinations blocked.

A shared gateway can give office systems consistent outbound policy. Its drawback is a wider outage impact, so assign ownership for availability and emergency changes.
A dedicated proxy limits the scope of a scheduling or eligibility integration. It's easier to isolate, but separate deployments can drift unless someone maintains a common review process.
Private connectivity can reduce public exposure where the provider supports it. Verify routing, failover, support access, and what metadata the provider retains.
Self-hosting gives your IT contractor direct policy control. Your practice still needs a named owner for patching, credential rotation, monitoring, and recovery.
Keep proxy credentials out of tickets and logs, expire session identifiers, and test credential rotation before an emergency. Understanding how encryption works also helps managers distinguish protected transport from permission to access patient information.
HIPAA obligations and technical recommendations aren't interchangeable. Access controls, audit controls, and transmission security belong in your Security Rule review; allowlisting and metadata blocking are implementation recommendations, not claims that a particular proxy configuration is legally sufficient.
HHS doesn't recognize an official HIPAA certification. Don't accept that label as proof of suitability, and don't assume encrypted forwarding automatically resolves business associate questions.
Use the PatientNotes guide to HIPAA BAAs to prepare vendor-review questions, then confirm the arrangement with qualified counsel or your compliance professional. Whether a provider needs a business associate agreement requires review of its actual role and handling of protected health information.
Are you trying to control outbound traffic, collect third-party records, or get a supported integration into production? Those are different purchasing decisions, and the lowest proxy traffic bill won't necessarily produce the lowest operating cost.
For a practice manager, a usable result might be an eligibility response attached to the correct account, an appointment update confirmed in the scheduling platform, or an authorized public record parsed into the required fields. A successful connection alone doesn't establish any of those outcomes.

Build, buy and hire paths compared
| Path | Best Fit | Hidden Cost | Primary Score |
|---|---|---|---|
| Manage proxies yourself | Internal egress control and modest volume | Engineer hours on rotation, retries and monitoring | Cost per usable result |
| Adopt a data API | Parsed records from protected sites | Less control and reliance on vendor coverage and pricing | Successful records per run |
| Hire engineers to build and run a proxy API | Custom destination policy, private networking, several internal teams | Build time and ongoing maintenance | Engineering hours per month and ban recovery time |
A managed data API becomes attractive when engineers spend more effort recovering access, rendering pages, and repairing parsers than using the resulting records. It isn't a substitute for an authorized clinical integration, and vendor coverage must be tested against your actual targets.
A conventional forward proxy remains appropriate for internal API testing, egress control, and traffic where you want fewer intermediaries handling contents. Custom engineering makes sense when private networking, destination policy, or shared internal infrastructure requires control a packaged service can't provide.
Calculate cost per usable result by dividing service charges, infrastructure, engineering labor, and manual recovery costs by completed results that pass your acceptance checks. Include practice staff time spent reconciling failures, not just the contractor's invoice.
Evaluate each option using:
When hiring, test CONNECT knowledge, credential handling, timeout design, observability, and runbook writing. Ask the candidate to explain how they'd investigate a tunnel that opens successfully but never returns application data.
Administrative staff should report symptoms and follow an approved downtime process, not change network security settings. Whether you're onboarding a virtual receptionist or prior-authorization support specialist, give that person a named technical escalation contact.
Choose the measures that matter most and run a time-limited pilot across normal and busy workflows. Define acceptance and rollback criteria before changing production routing.
A proxy server API provides a control point for outbound connections, not a complete security or staffing solution. Choose a forward proxy for destination control, a managed data API for suitable record-collection work, and engineering support when your integration needs custom policy or networking. Judge the arrangement by usable outcomes and maintenance effort rather than traffic price alone.
For a medical practice, the next step is to map required destinations, identify who owns failures, and test the chosen approach with synthetic data. Keep credentials out of logs, distinguish authentication failures from upstream outages, and measure the delays staff experience during patient-facing work. Confirm access-control, audit, and business associate questions with qualified professionals before routing protected health information through a new service.
If your pilot points toward custom development, HireDevelopers.com can help you explore backend and DevOps candidates. Bring your destination map, failure scenarios, and acceptance criteria so the conversation starts with the work your practice needs.

Wondering what is technical leadership? Discover the essential skills that transform great engineers into the influential leaders your team needs.


Unit economics measures whether one repeatable unit of business, such as one customer, subscription, or staffed engagement, generates more contribution than it costs to acquire and serve, before fixed overhead is counted. For a medical practice, the unit might be a remote staffing engagement; for a software team, it might be one developer engagement or...

So, you need to hire someone. Great. Hope you enjoy spending your afternoons fact-checking résumés and running technical interviews—because that’s now your full-time job. Or you could do what smart founders do: try before you buy. That’s what contract to hire means. It's a paid, real-world audition for a potential full-time role. It’s your sanity...


