Agile Software Development Teams Guide

Victor
Posted on 20 October 2026
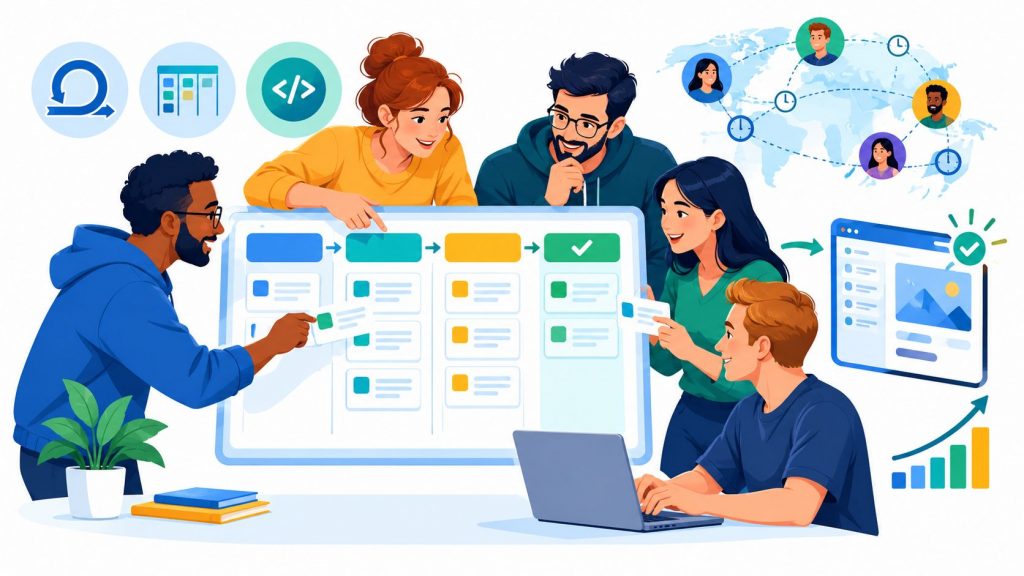


The most popular advice about agile software development teams is also the least useful: run the ceremonies, name the roles, and delivery will improve. It won't, at least not reliably. Daily standups, sprint planning, retrospectives, and a board full of tickets can coexist with unclear ownership, unstable releases, constant rework, and a product backlog nobody trusts. What separates effective teams is not the label on the process. It's whether the organization gives a small, cross-functional group clear decision rights, testable work, a dependable delivery platform, fast feedback, and balanced measures of speed and stability. That answer matters even more when you're scaling across time zones, vendors, or employment models, because distance exposes weak foundations quickly. Adding developers or AI tools to a confused system usually produces more code to coordinate, review, and fix. This guide sets out the operating rules behind agile, how to structure accountabilities, how to scale distributed teams without losing control, how to govern AI-generated code, and how to measure performance without rewarding unsafe delivery.
Table of Contents
An organization can call itself agile while its teams wait days for decisions and weeks for approvals. New terminology and sprint calendars do little when requirements stay vague, work passes between separate functions, and teams cannot change course. The process may look iterative while delivery remains sequential.
Team conditions provide a better diagnostic than the label. Research summarized by Scrum.org examined 4,940 team members in 1,978 Scrum teams. The team-process factors studied statistically explained 75.6% of variation in team effectiveness, 34.9% in team morale, and 57.9% in stakeholder satisfaction, according to Scrum.org's summary of the evidence-based business case for agile. These findings do not establish that Scrum alone causes good outcomes. They do show why leaders should examine collaboration, goal clarity, role design, feedback, and delivery discipline.
Survey results cited in the same Scrum.org summary reveal a gap between organizational claims and team practice: 94% of respondents said their organizations practiced agile, and 98% reported success from agile projects, while more than half of their teams had not yet adopted agile. An enterprise can endorse agile without giving its teams the authority or access to work that way.
That gap shows up when teams wait for product decisions. A group still needs someone who can order the work, engineers who can build and test it, access to users or stakeholders, and room to adjust scope as evidence changes.
An agile team is defined by how quickly it can turn a clear outcome into working software, learn from use, and adapt without destabilizing delivery.
Before adding contractors, nearshore engineers, or another vendor, assess the conditions they will inherit. Can the team make progress without waiting on outside decisions? Are environments and test data available? Do dependencies sit within the team, or with groups working to different schedules? Track review delays, blocked work, incident load, and how often tasks return for clarification.
Global staffing can add capacity when the work is bounded and the receiving team has sound operating conditions. It cannot replace product ownership or a platform that supports safe delivery. Without those foundations, adding people increases coordination, unfinished work, and opportunities for misunderstanding. Establish clear decision rights and remove recurring delivery bottlenecks before expanding the team.
Agile wasn't created as a universal project-management method. It was formally established on February 11-13, 2001, when 17 software practitioners met at The Lodge at Snowbird in Utah, as documented in the Agile Alliance history of the Agile Manifesto. Participants represented approaches including Extreme Programming, Scrum, DSDM, Adaptive Software Development, Crystal, Feature-Driven Development, and Pragmatic Programming. They were looking for shared principles across lightweight methods, not a single prescriptive process.
The Manifesto expressed four preferences: individuals and interactions over processes and tools, working software over documentation, customer collaboration over contract negotiation, and responding to change over following a plan. Those are preferences, not bans. Documentation, contracts, plans, and tools still matter. They just shouldn't become substitutes for conversation, usable software, collaboration, or adaptation.
The supporting principles are more concrete than many summaries suggest. They call for delivering working software frequently, having business stakeholders and developers work together daily, sustaining a pace that can continue indefinitely, treating working software as the primary measure of progress, and reflecting regularly before adjusting behavior, as set out in Atlassian's presentation of the Agile Manifesto principles.
For a distributed team, those ideas become operating requirements. Stakeholders need a reliable response window. The team needs an explicit definition of working software, not code sitting on a branch. Retrospectives need owners and follow-through. Sustainable pace also has a practical meaning across time zones: don't design a process that depends on the same people attending early-morning and late-night meetings indefinitely.
Timeless principles still need context-specific execution. Mobile work, for example, adds app review, device fragmentation, and release-train constraints, which is why it can help to compare your setup against agile best practices for mobile teams before copying a web team's cadence wholesale.
Scrum fits product work where a team can commit to a goal for a short timebox, inspect a usable increment, and adapt the backlog. It's less comfortable when work arrives as constant interruptions or when nobody can protect the sprint goal.
Kanban fits support, platform, and operational streams where priorities change continuously and limiting work in progress matters more than planning a fixed batch. It still needs explicit policies, feedback, and improvement. A board with unlimited work in progress is only a visualization of overload.
Extreme Programming, or XP, emphasizes engineering discipline through practices such as test-driven development, pair programming, continuous integration, and small releases. It's especially relevant when quality problems, rather than planning problems, constrain delivery. Many strong teams combine Scrum's planning rhythm with Kanban flow limits and XP engineering practices. If you're weighing the trade-offs, a detailed comparison of Agile, Kanban, and Scrum can help separate the umbrella philosophy from the specific frameworks.
| Framework | Best For | Cadence | Key Focus |
|---|---|---|---|
| Scrum | Product increments with a clear sprint goal | Fixed sprint, commonly one or two weeks in this guide's cited study context | Inspection, adaptation, and a usable increment |
| Kanban | Support, platform, and interrupt-driven work | Continuous flow | Work-in-progress limits and lead time |
| XP | Quality-critical product engineering | Short iterations with continuous integration | Testing, pairing, refactoring, and technical excellence |
| Hybrid | Mixed product and operational demand | Planned iterations plus flow policies | Predictability without ignoring urgent work |
Cadence isn't a matter of taste. In a comparative study of four software projects, daily planning produced 23 days of delivery delay and 57 defects, weekly planning produced 8 days and 32 defects, and two-week sprint planning produced approximately 1-2 days of delay and 17-23 defects, according to the MDPI comparative study of sprint duration and delivery outcomes. Treat that as context-dependent evidence, not a universal law.
The practical lesson is to avoid planning horizons so short that developers spend their time re-planning instead of finishing. A one- or two-week cadence often gives distributed teams enough inspection without excessive overhead. Validate your choice with lead time, escaped defects, blocked-work duration, and unplanned work, not velocity alone. If quality and flow deteriorate, the calendar is part of the system you need to adjust.
Role confusion is one of the fastest ways to slow a distributed team. A client assumes the vendor owns product decisions. The vendor assumes the client will accept work. A project manager coordinates status but can't remove impediments, and developers wait because nobody is accountable for the next decision. The titles matter less than whether each accountability has a named owner.
The 2020 Scrum Guide specifies a Scrum Team with one Scrum Master, one Product Owner, and Developers, with no sub-teams or hierarchies, and recommends typically 10 or fewer people, according to the official 2020 Scrum Guide. The whole team is accountable for a valuable, useful increment every sprint. Within that shared accountability, the work still divides clearly.

The Product Owner is accountable for maximizing product value. That means ordering the backlog, making trade-offs visible, and ensuring stakeholders understand what won't be built yet. A committee can't perform this accountability well if every decision needs consensus from people outside the team.
The Scrum Master is accountable for establishing Scrum and improving team effectiveness. In practical terms, that includes coaching, removing impediments, protecting focus, and making process problems visible. It's not a meeting-secretary role, and it's not a delivery enforcer who reports individual velocity to management.
Developers are accountable for creating the usable increment. In Scrum, that term covers the people who design, build, test, and deliver the work, not only people who write application code. If quality engineering, UX, data, or DevOps skills are required every sprint, the team needs dependable access to them. Borrowing specialists through a ticket queue creates a hidden sub-team and a predictable bottleneck.
Cross-functional doesn't mean interchangeable. It means the team contains enough skills to finish valuable work without routine handoffs. A backend specialist can still review a simple frontend change, and a QA engineer can shape acceptance criteria before development starts. The goal is shared ownership of the increment, not dilution of expertise.
When external engineers join, document decision rights in plain language. Who can merge to the main branch? Who approves an architecture change? Who speaks to customers? Who can stop a release? Who accepts a story? Those answers should be available asynchronously, because a distributed team can't rely on whoever happens to be online.
Practical rule: If a decision regularly waits for a person outside the team, either move the decision into the team, give the team a clear escalation window, or admit that the dependency is part of your delivery system and plan for it.
Acceptance criteria connect product intent to implementation and verification. A mixed-methods case study of eight agile teams analyzed 1,345 user stories across 19 sprints and found a weak positive relationship between acceptance criteria and on-time completion, while overall story quality and the mere presence of test cases showed no clear relationship with fulfillment efficiency, according to the Utrecht University case study on acceptance criteria and fulfillment efficiency.
That result warns against documentation for its own sake. Useful criteria describe observable behavior. They state what a user can do, what the system returns, which errors appear, and what data changes. They also define boundaries, such as permissions, empty states, and failure handling.
For teams across time zones, good criteria reduce the need for synchronous clarification. They don't replace conversation. They make the conversation happen earlier, when changing direction is still cheap, and they give the next person who picks up the work enough context to proceed responsibly.
Scaling across borders changes more than payroll. It changes overlap hours, review patterns, documentation habits, escalation paths, and the cost of ambiguity. A team that works well in one office because people can tap a colleague on the shoulder may struggle when a question waits overnight. The answer isn't more meetings. It's designing the work so that progress doesn't depend on constant synchronous access.
Start with the shape of demand. A stable product team benefits from long-lived membership and shared ownership of a domain. A short migration, integration, or remediation effort may need a temporary team with a narrow outcome and a clear exit. Staff augmentation can work when your existing leads can direct and review the work. A complete outsourced team needs stronger product and architecture governance from you, not less, because you're delegating more of the delivery system.
Nearshore arrangements can provide more overlapping hours for planning, pairing, and incident response. Offshore arrangements can broaden the talent pool and support follow-the-sun work, but they require cleaner handoffs and more disciplined written decisions. Neither model is automatically cheaper once rework, management time, attrition, and delayed feedback are included.
Be honest about internal capacity. If your senior engineers have no time to review code, adding junior developers in another country will create a queue. If your Product Owner can't attend refinement or accept increments, a larger team will produce more unaccepted work. If your architecture requires constant coordination between components, splitting those components across vendors will amplify the dependency.
HireDevelopers.com is one example of a global talent platform that presents vetted engineers for full-time, part-time, individual, or team engagements and handles payroll and compliance support. Whether you use a platform, an agency, or direct employment, vet the same things: technical depth, communication, domain fit, availability in your working window, and evidence that the person can work from written acceptance criteria without constant supervision.
Onboarding should end with a small, real change moving through the full path to production or a production-like environment. Reading documents isn't enough. A new engineer needs repository access, environment setup, test data, deployment permissions appropriate to the role, incident channels, coding standards, and a named buddy who can answer questions during overlap hours.
Give the first assignment a narrow scope and strong acceptance criteria. Pair the new engineer with a reviewer who explains local conventions instead of only requesting changes. Record architecture decisions and operational runbooks where the team already works. Tools such as Slack, Microsoft Teams, Jira, Linear, GitHub, and GitLab can support that record, but only if the team treats written updates as part of delivery.
The coordination lesson applies outside product engineering too. Teams that maintain several client properties need consistent ownership and update routines, similar to the discipline described in tips for handling several WordPress sites. The technology differs, but unmanaged variation creates the same operational drag.
Good remote management relies on visible work, not visible people. A useful board shows blocked items, review queues, work in progress, and who owns the next action. Async updates should state what changed, what's blocked, and what decision is needed. Live meetings should be reserved for ambiguity, conflict, design exploration, and relationship building. For broader routines, practical guidance on managing remote development teams can help you formalize communication without turning every update into a status call.
Psychological safety has operational consequences. Engineers who fear blame hide risks until a sprint review or production incident forces the issue. Leaders should ask what the team needs, respond to bad news without punishment, and separate system problems from individual performance. Blameless incident reviews, explicit working agreements, and rotating facilitation help distributed members participate as team members rather than as an external labor pool.
Scale in increments. Add a small group, observe review latency and rework, and fix the constraints that appear before adding more people. That is slower than announcing a large team on day one, but it's much more likely to increase finished, reliable work.
AI coding assistants change the economics of writing code faster than they change the cost of understanding, reviewing, securing, and operating it. That's the governance problem agile teams now face. If generation becomes cheap but verification capacity stays fixed, the bottleneck moves to pull requests, testing, security review, and production support. Throughput can rise on a dashboard while delivery stability gets worse.
Recent DORA research covering nearly 5,000 technology professionals found that 90% use AI at work and more than 80% believe it improves productivity, yet AI adoption remains negatively associated with delivery stability, according to Google's summary of the 2025 DORA report. The same research reports that 30% of developers have little or no trust in AI-generated code. That isn't an argument against AI. It's evidence that confidence, verification, and accountability need explicit design.
If you're evaluating the tooling layer, comparisons of AI tools for faster app launches can be useful for understanding generation features. Tool selection is still the easier decision. Your Definition of Done, review policy, and sprint capacity determine whether the output is safe to ship.

The engineer who submits the change owns it. AI can draft code, tests, documentation, or migration scripts, but it can't be accountable for correctness, licensing, security, or customer impact. Your pull request template should make that ownership visible by asking what was generated, what the author changed, how the behavior was verified, and which risks remain.
Risk-tier the work. A generated unit test for a pure function needs a different control from an authentication change, payment flow, data migration, infrastructure policy, or cryptographic routine. High-risk items should require human design review, threat modeling where relevant, and reviewers with domain expertise. Low-risk, repetitive work can move through standard automated checks and peer review.
Refinement should identify where AI is likely to help and where it may create verification debt. Boilerplate, test scaffolding, documentation drafts, and repetitive transformations are different from novel business rules or poorly understood legacy behavior. If the team can't explain the expected behavior before generation, AI will produce plausible code for the wrong problem.
Estimation needs to include auditing time. Don't reduce story size just because the first draft appears quickly. Account for reading the code, checking edge cases, running tests, reviewing dependencies, and updating observability. Sprint capacity should reflect the team's review capacity, especially when senior engineers become the control point for every AI-assisted change.
Your Definition of Done should cover:
A team that generates code quickly but creates more incidents hasn't become more productive. Measure the full path: clarification, generation, review, rework, deployment, failure, and recovery. Watch whether review queues grow, whether escaped defects increase, and whether senior engineers spend so much time auditing that design and mentoring suffer.
Distributed teams need extra care because AI policies can vary by client, vendor, country, and codebase. Put the approved tools, prohibited data, disclosure expectations, and review tiers in the working agreement. Then inspect the results in retrospectives. The useful question isn't whether AI made someone type faster. It's whether the team delivered a reliable increment with less total effort and risk.
Velocity is easy to count and easy to misuse. Story points are a planning aid inside a team, not a currency for comparing teams or judging individuals. When managers reward points, teams inflate estimates, split stories artificially, avoid difficult quality work, or ship changes that create incidents later. The number improves while the product and the delivery system get worse.
A balanced view pairs throughput with instability. DORA's framework uses five metrics: throughput includes change lead time, deployment frequency, and failed-deployment recovery time, while instability includes change fail rate and deployment rework rate, according to DORA's history of its software delivery metrics. Deployment rework rate was added in 2024 after researchers identified deployment-related rework as a distinct indicator. That combination prevents a team from looking successful merely because it ships often.

Change lead time measures the time from code commit to successful production deployment. Long lead time can point to review queues, manual approvals, fragile pipelines, large batches, or environment problems. Shortening it by skipping tests isn't improvement. It's risk transfer.
Deployment frequency shows how often the team can release. Frequent deployment usually requires small changes, automation, and confidence in rollback. On its own, though, it can reward rushed work.
Failed-deployment recovery time measures how quickly the team restores service after a failed deployment. It reflects observability, rollback design, incident roles, and the ability to make decisions under pressure.
Change fail rate is the percentage of deployments that cause production failures. Deployment rework rate is the percentage of deployments consisting of unplanned work to fix defects or incidents. Together, they show whether speed is being purchased with instability.
A fast team that repeatedly breaks production isn't high-performing. It's creating urgent work for itself and calling the activity delivery.
DORA metrics describe delivery performance, but they don't explain everything a manager needs. Add blocked-work duration, review latency, unplanned-work percentage, escaped defects, and the age of work in progress to locate constraints. Add customer outcomes, such as adoption of a released feature, task success, support demand, or stakeholder satisfaction, to check whether the team is building the right thing.
If you need a broader measurement catalogue, a structured overview of software development key performance indicators can help you choose indicators without turning every activity into a target. Keep the set small enough that the team can discuss it and act. A dashboard nobody uses in planning or retrospectives is reporting overhead.
Use metrics to ask better questions:
Never use delivery metrics to rank individual engineers. Software delivery is a team system with shared queues, dependencies, and risks. Individual targets encourage local optimization: fast approvals, unreviewed merges, narrow story selection, and reluctance to help with incidents or mentoring.
Review trends with the team and let the team propose experiments. For example, limit work in progress for two sprints and observe lead time and blocked time. Add a review rotation during overlap hours and observe review latency and change fail rate. Reduce batch size for a risky service and observe recovery time and rework. The point is disciplined learning, not dashboard compliance.
Balanced metrics also help you validate scaling decisions. If adding engineers increases deployment frequency but doubles review queues and rework, capacity didn't scale. The constraint moved. If lead time, failure, recovery, and customer outcomes improve together, you have stronger evidence that the team design is working.
Effective agile software development teams are built, not declared. They need a clear product outcome, explicit accountabilities, testable acceptance criteria, dependable engineering platforms, and feedback from people who use or fund the work. Frameworks help when they fit the work. They harm when leaders use ceremonies to avoid harder decisions about ownership, quality, dependencies, and capacity.
Global staffing and AI can expand what a team is able to attempt, but both amplify the existing system. Strong teams use additional capacity and automation to finish reliable increments faster. Struggling teams use them to create more work in progress, more review debt, and more production risk. That's why diagnosis should come before scale.
Use the next month to inspect the system your team works in. Don't start by changing every ceremony. Gather evidence, choose a small number of constraints, and run visible experiments.
The goal isn't to become more agile in appearance. It's to deliver working software at a sustainable pace, learn from customers, and keep quality visible while you adapt. If your team can do that with the people it has now, scaling becomes a manageable engineering decision. If it can't, fix the foundations before asking more people or smarter tools to compensate.
If you're ready to add capacity to a team with clear ownership and a healthy delivery system, book a consultation to discuss the skills, time-zone coverage, and engagement model you need. Request a shortlist of vetted engineers, interview candidates against your acceptance criteria and working agreements, and start with a small increment that proves fit before you scale further.

You probably didn't start a company because you love reading resumes that all say “built scalable systems” and “worked cross-functionally.” Translation: this person once touched Kubernetes and survived three sprint retros. Hiring engineers gets ugly fast. One open role becomes five. Your lead engineer is suddenly running intro calls. Your product manager is “helping with...

Here’s the simple, no-BS truth on managed services vs. staff augmentation: Managed services sell you a finished outcome. Staff augmentation sells you skilled people you manage yourself. Your choice boils down to a single question: do you want to hand over the keys, or do you want your hands glued to the steering wheel? The...

Let’s get one thing straight. Outsourcing is hiring another company to do a job. Offshoring is building your own team in another country. Think of it like this: you can rent a professional catering service for a party, or you can build a second kitchen in another city and hire your own chefs. Your choice...


